Controlled trial · 26 Oct 2026
Does splitting a feature across coding agents beat one agent?
A planner split each of six features into three parts, and three Codex coders built them at the same time. Whether each coder saw only its own part's requirements or the whole task, the team passed no more of the hidden acceptance tests than one agent did (61.6% and 52.9% against 62.4%), at 2.3 to 2.5 times the cost and with no saving in time. The split added a new failure: parts that didn't fit, so the application wouldn't start.
The question
When a planner splits a feature into parts for coding agents working at the same time, does the team get more of it right than one agent, and does giving each coder only its part's requirements lose details at the joins?
- Experiment
- SPS
- Runs
- 144
- Agents
- Codex CLI 0.157, subagents via multi_agent_v2 (team arms) (gpt-5.6-luna (hosted))
Key findings
SPS-1Splitting a feature across three coders working at the same time, each given only its part's requirements, passed 61.6% of hidden acceptance tests; one agent alone passed 62.4%, at less than half the cost
- cost per run: one agent $0.073, split team $0.167; median time 2.3 and 3.8 minutes, although the three coders worked at the same time in every run
- the planner's part files carried every field name and status code the tasks stated, and more of them reached the code than in any other setup (88%)
- with every coder reading the whole task the split scored 52.9%, and a team with one coder 53.9%: no measurable differences
Limitsone model at one effort level, six features of moderate size in one Java codebase, team instructions written by me; a gap under about 15 points would usually not show
Source ↗−0.8 pts
Interval includes zero
95% interval −11.5 pts to +9.3 ptsbootstrap 95% CI within tasks; two-sided permutation test, Holm p 1.0
Measureshare of hidden tests passed (higher is better), split team minus one agent, mean over six features
Sample72
SPS-2In 4 of 72 split runs the application would not start at all, against none of 36 one-agent runs
- two were parts that didn't fit: two controllers with the same name from different coders, and a class one coder relied on that another never registered
- the other two were one coder's own wiring mistake that no agent caught, because no one started the whole application
- the reviewer approved one of these runs
Limitsthe causes come from checks made after the runs; a team with one coder had 1 such run in 36
Source ↗4 of 72
Measureruns where the application failed to start, so no hidden test could pass (lower is better)
Sample108
SPS-3Agent reviewers approved code that failed hidden acceptance tests 14 times out of 15
- team with one coder 4 of 4, split with parts only 5 of 6, split with the whole task 5 of 5
- agents claimed success while hidden tests failed in 28 to 34 of 36 runs in every setup
Limitsthe hidden tests are stricter than what the reviewer was asked to check
Source ↗14 of 15
Measurefinal reviews that approved, and of those, changes failing hidden tests
Sample108
Question
In the swarm-tax experiment, one agent beat a planner–coder–reviewer team, and giving every agent the task file only brought the team level. But that team didn’t really split the work: the planner gave the whole feature to one coder.
The usual pitch for multi-agent coding is the split: a planner divides a feature into parts, and several coders build them at the same time, each with a focused brief. So this experiment tests that.
The short version: the split happened exactly as designed, and the briefs were good, but the team got no more of each feature right than one agent did. It cost more than twice as much, wasn’t any faster, and added a new way to fail: parts that didn’t fit together.
I wanted to know three things:
- does a team that splits a feature, each coder given only its part’s requirements, beat one agent?
- does giving each coder only its part lose details at the joins, compared with letting every coder read the whole task?
- once every agent can read the whole task, does splitting the work beat a team with one coder?
Prediction
Before the runs, I published the design, three hypotheses and how I’d read each result (README.md):
- H1. The split team, each coder seeing only its part, and one agent differ.
- H2. The split team with every coder reading the whole task, and the split team seeing only parts, differ.
- H3. The split team reading the whole task, and a team with one coder reading the whole task, differ.
The design also said when a split setup wouldn’t count: if fewer than half its runs had two or more coders, or if coders meant to see only their part opened the full task in more than a quarter of runs.
Set-up
The agent:
- Codex CLI 0.157 with the hosted
gpt-5.6-lunamodel at medium reasoning effort, in every agent and subagent. - Teams use Codex’s own subagents, each starting with no conversation history. Codex runs up to four agents at once, the planner included, so up to three coders can work at the same time.
- Each run in a fresh copy of shopizer, an open-source Java shop, in a sandbox that shows the agent only its own copy.
Four setups, all run in the same hours:
| Setup | What happens |
|---|---|
| One agent | Gets the task and does it |
| Team, one coder | As swarm-tax’s best team: a planner (not allowed to edit code) briefs one coder; a fresh reviewer checks; one round of fixes. The task is in the repository and the coder and reviewer read it |
| Split, parts only | The planner splits the feature into parts and writes a brief for each: what it does, the files it owns, every requirement that applies to it in the task’s exact words, and what the other parts provide. One coder per part, all at once, each reading only its own brief. A fresh reviewer reads the whole task and checks the whole change; one round of fixes, each fault sent to the coder who owns it |
| Split, whole task | As above, but every coder reads the whole task first and then its own brief |
Because the briefs are files on disk, I could read exactly what each coder was told, unlike the encrypted messages between agents in swarm-tax.
The tasks: swarm-tax’s six features, unchanged: discount codes, quantity price tiers, a wishlist, back-in-stock alerts, product questions with moderation, and cart limits. Each has 13 to 16 hidden acceptance tests that the agents never see.
Scoring: the share of a feature’s hidden tests the code passes. Higher is better: 100% means the feature works as the task asked. 6 runs per feature per setup: 144 runs.
Results
Findings SPS-1 to SPS-3 are at the top of the page.
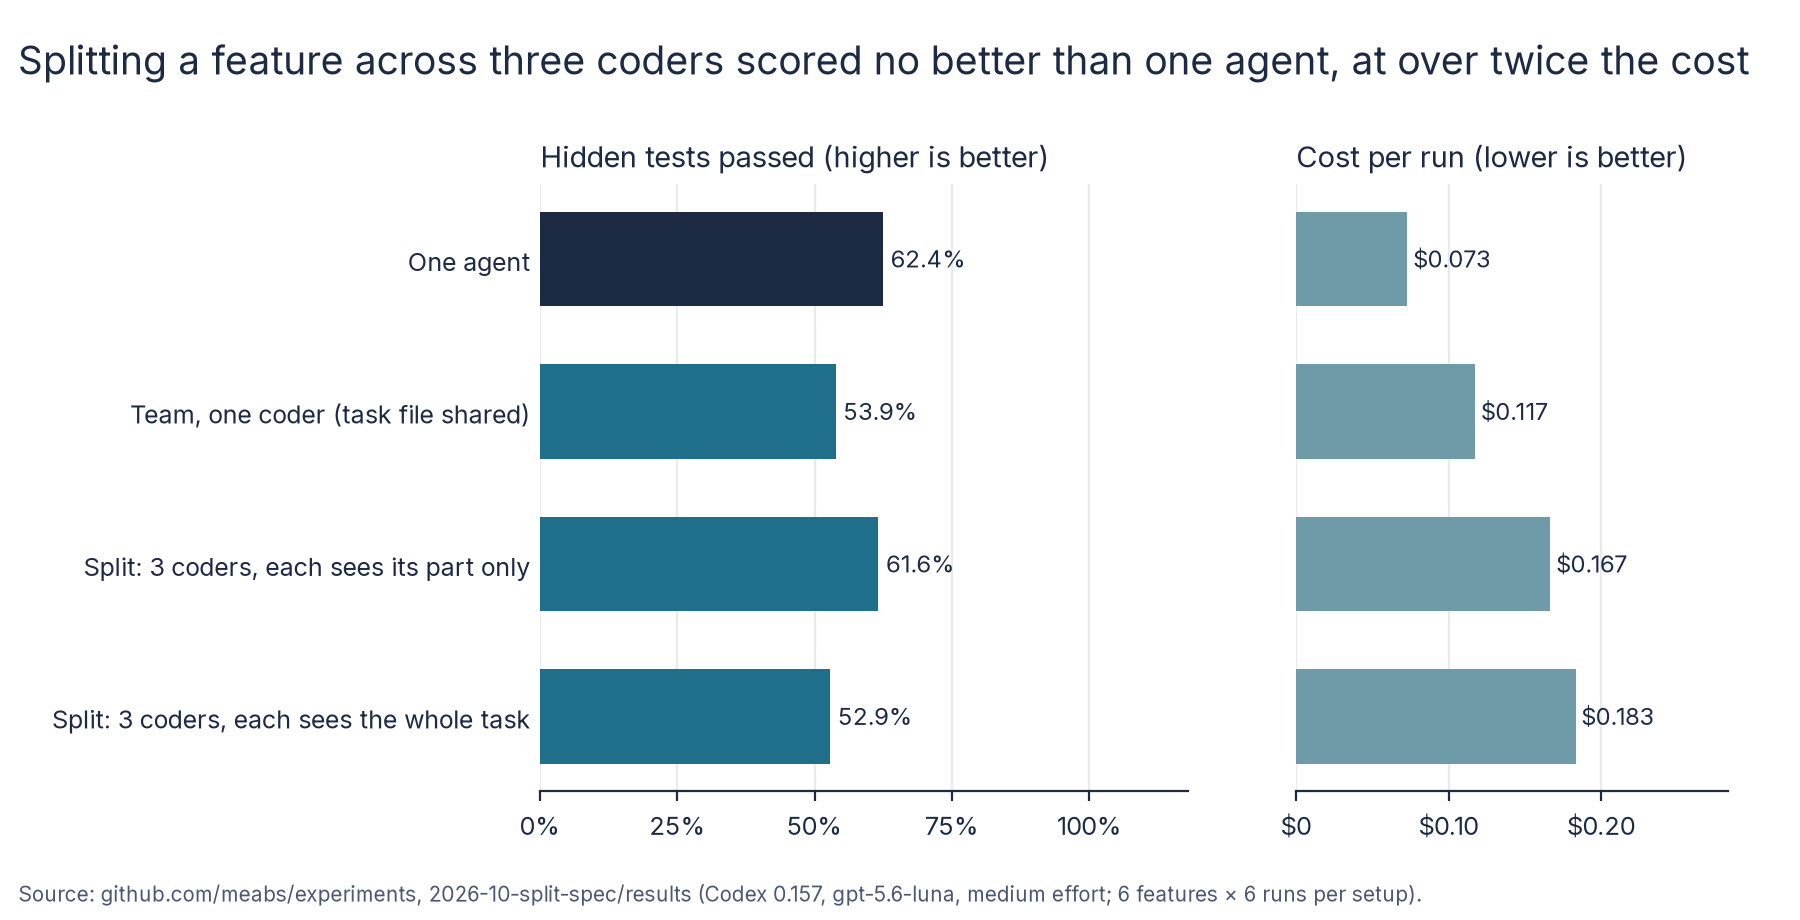
The split happened, and didn’t help
In all 72 split runs the planner wrote three briefs and started three coders, and in every run the coders worked at the same time. Planners mostly split by layer: data and service, customer-facing API, admin or report API. Coders kept to their briefs: of the 108 meant to see only their part, 2 opened the full task.
Share of hidden tests passed, by feature (higher is better):
| Feature | One agent | Team, one coder | Split, parts only | Split, whole task |
|---|---|---|---|---|
| Back-in-stock alerts | 52.6% | 30.8% | 34.6% | 37.2% |
| Cart limits | 50.0% | 46.4% | 69.0% | 77.4% |
| Discount codes | 33.3% | 24.0% | 49.0% | 25.0% |
| Product questions | 86.9% | 72.6% | 83.3% | 57.1% |
| Price tiers | 58.3% | 91.7% | 69.0% | 59.5% |
| Wishlist | 93.3% | 57.8% | 64.4% | 61.1% |
| Mean over features | 62.4% | 53.9% | 61.6% | 52.9% |
Each setup wins somewhere; across the six, none stands apart. One agent and the one-coder team scored close to their swarm-tax results (56.8% and 54.1%), a check that nothing changed between the experiments.
Good briefs weren’t enough
The planners did what you’d hope for. In the parts-only split, every field name and status code each task stated appeared in the briefs, and more of them reached the code (88%) than in any other setup (one agent 84%). Swarm-tax’s lesson, keep the requirements intact through the hand-off, was followed. It didn’t raise the score. The tests that failed were mostly about behaviour (rounding, ordering, which records count), not names.
Parallel work saved no time
The three coders worked at the same time in every split run, but the median run took 3.8 minutes, the same as the one-coder team and well over one agent’s 2.3. Planning, review and the fix round used up whatever the parallel work saved.
A new failure: parts that don’t fit
When the application won’t start, no hidden test can pass, and the run scores 0%. That happened in 4 of 72 split runs, 1 of 36 one-coder team runs, and none of the one-agent runs:
- two controllers with the same name in different places, both edited by more than one coder;
- a class one coder wrote without registering it, which another coder’s code depended on (the reviewer approved this run);
- twice, a single coder’s own wiring mistake, which nobody caught because no agent started the whole application.
The reviewer still approved broken code
14 of 15 reviewer approvals went to code that failed hidden tests. Agents claimed success while hidden tests failed in 28 to 34 of 36 runs, in every setup.
Hypotheses
| # | Comparison | Difference (points of hidden tests passed) | 95% interval | Holm p | Verdict |
|---|---|---|---|---|---|
| H1 | split, parts only − one agent | −0.8 | −11.5 to +9.3 | 1.0 | No measurable difference |
| H2 | split, whole task − split, parts only | −8.7 | −20.6 to +3.2 | 0.60 | No measurable difference |
| H3 | split, whole task − team, one coder | −1.0 | −12.4 to +9.8 | 1.0 | No measurable difference |
A negative difference means the first setup did worse. The Holm p is the chance of a difference this large if there were really none, corrected for testing three hypotheses; below 0.05 counts as measurable. “No measurable difference” means the test couldn’t tell the setups apart, not that they’re proven equal: with six features, a gap under about 15 points would usually look like this.
Cost
| One agent | Team, one coder | Split, parts only | Split, whole task | |
|---|---|---|---|---|
| Cost per run (lower is better) | $0.073 | $0.117 | $0.167 | $0.183 |
| Cost per hidden test passed (lower is better) | $0.008 | $0.015 | $0.019 | $0.024 |
| Median time per run (lower is faster) | 2.3 min | 3.9 min | 3.8 min | 3.7 min |
Checks on the runs
- All 144 runs finished and were graded; none timed out or hit a usage limit. The runs were paused once for a usage limit on my side and restarted; the runs in progress at the pause were discarded and rerun from scratch.
- Model and effort were checked in all 504 session files, subagents included.
- No agent could see the hidden tests: every command was audited from the session files.
- What each coder read and wrote comes from its own commands, not from the agents’ summaries.
Limits
- One model at one effort level, six features of moderate size in one Java codebase, and team instructions I wrote. Bigger features, which one agent can’t hold in view, could come out differently.
- Six features is few. A gain or loss under about 15 points can’t be ruled out.
- “Read only your part” was an instruction, checked afterwards from each coder’s commands.
- The causes of the start-up failures come from checks made after the runs.
What this means: impact and risks
This part is my interpretation, not a measurement.
Splitting work across agents is not a free upgrade either. On features of this size, a split team cost more than twice as much as one agent, wasn’t faster, and got no more of the feature right. Measure a split against one agent on your own work before adopting it.
The risk moves to the joins. One agent builds a whole that works or doesn’t. A split team can build parts that each look fine and don’t fit: two controllers with the same name, or a class one coder depends on that another never set up. Those failures take down the whole application, not one feature, and here an agent reviewer approved one of them. If you split work across agents, build and start the whole application after the parts are joined, and don’t count a reviewer agent’s approval as that check.
Good hand-offs are necessary, not enough. Keeping the requirements intact brought swarm-tax’s team level with one agent. Here, near-perfect briefs still didn’t take a team past it.
Agent approvals and success reports are still not evidence. In every setup, most claims of success and nearly every reviewer approval went to code that failed its acceptance tests.
What to do about it:
- Compare any split or team setup against one agent on your own tasks, with cost and time recorded.
- After a split, have something build, start and exercise the whole application before review.
- Keep your own acceptance tests; don’t rely on an agent’s approval or report.
What would be worth testing next?
These are proposals, not results.
- A split team with a build-and-start step: one agent starts the application and calls each new endpoint once before review.
- Teams that must write tests from the requirements before coding.
- Bigger features, where one agent’s context fills up and a split has something to gain.
Reproduce
Everything is in experiments/2026-10-split-spec:
- the tasks, hidden tests and reference implementations (
tasks/,hidden/,reference/); - the team instructions (
arms/); - the grader, trial generator and session audit (
scripts/); - every run’s grading files, diff, the planner’s briefs, event stream and session audit (
results/); - the analysis and chart scripts (
scripts/analyse.py,scripts/charts.py).
The commands are in REPORT.md, section 10.
Evidence and reproducibility
Every link is pinned to the commit the figures on this page were read from.
Question, correction, or a result that differs from mine? Join the discussion ↗