Review

Review, merging and risk: matching scrutiny to consequence.

Findings

18 findings, each linking to its write-up and limits

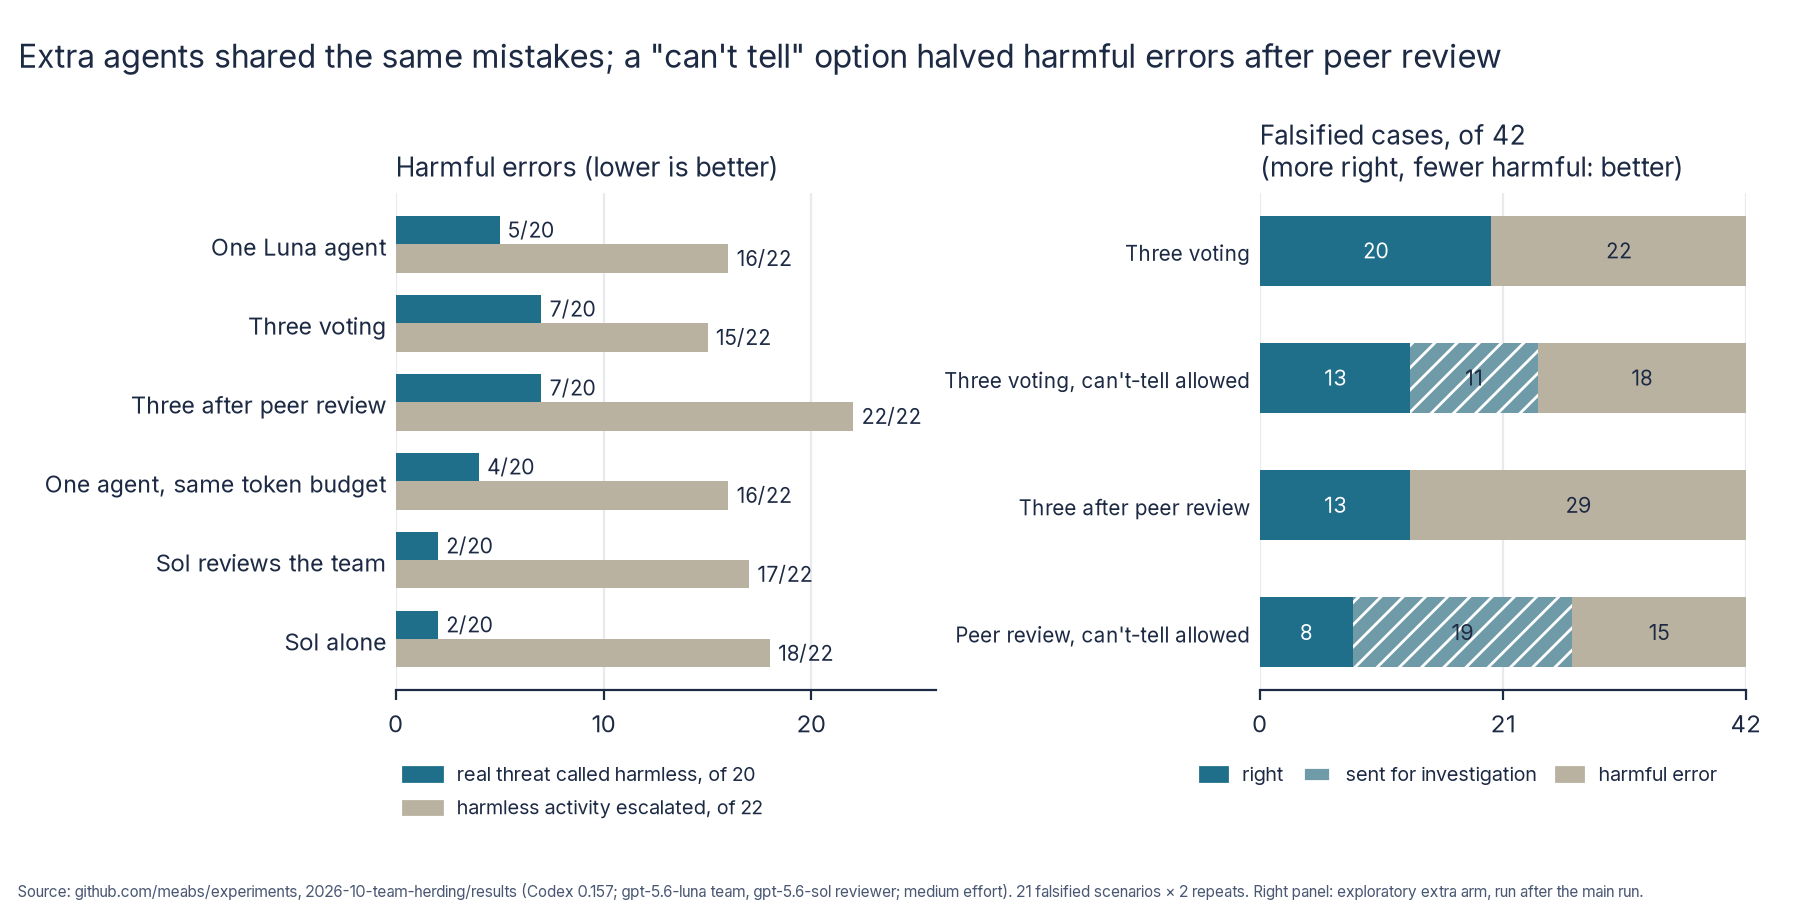
  • TH-1A vote of three identical agents was no better than one agent at seeing through a false fact20 vs 17 of 42
  • TH-2After reading each other's conclusions, all three agents escalated every harmless alert whose records conflicted22 of 22
  • TH-3A stronger model reviewing the team rarely overruled it, and did no better than on its own6 of 42
  • TH-4Allowing a "can't tell, investigate" answer for conflicting evidence halved the peer-reviewed team's harmful errors, by sending 19 of 42 falsified case-repeats to a human (exploratory)29 → 15
  • SPS-1Splitting a feature across three coders working at the same time, each given only its part's requirements, passed 61.6% of hidden acceptance tests; one agent alone passed 62.4%, at less than half the cost−0.8 ptsInterval includes zero
  • SPS-2In 4 of 72 split runs the application would not start at all, against none of 36 one-agent runs4 of 72
  • SPS-3Agent reviewers approved code that failed hidden acceptance tests 14 times out of 1514 of 15
  • SWT-1A planner–coder–reviewer team passed 25.7% of the hidden acceptance tests; one agent alone passed 56.8%, for less money−31.2 ptsInterval excludes zero
  • SWT-2Giving every team member the task file raised the team from 25.7% to 54.1% of hidden tests passed, level with one agent, at about 1.6 times its cost+28.5 ptsInterval excludes zero
  • SWT-3Every time an agent reviewer approved a change, the change failed hidden acceptance tests: 24 of 24 approvals24 of 24
  • DJ-1Shown the task and the diff, the AI judge called 57 of 96 changes right: it caught 21 of 48 broken changes and passed 36 of 48 working ones, no measurable difference from guessing0.59Interval excludes zero
  • DJ-2Showing the judge the agent's own success report did not make it miss more broken changes: it caught 20 of 48 with the report and 21 without21/48 vs 20/48
  • DJ-3A fixed doubtful report ('I could not run the tests') made the judge catch more broken changes (30 of 48) but pass fewer working ones (22 of 48); it got no more accurate overall+21 pts, −25 pts
  • DJ-4The judge's confidence did not track whether it was right: it averaged 87 out of 100 when right and 86 when wrong87 vs 86
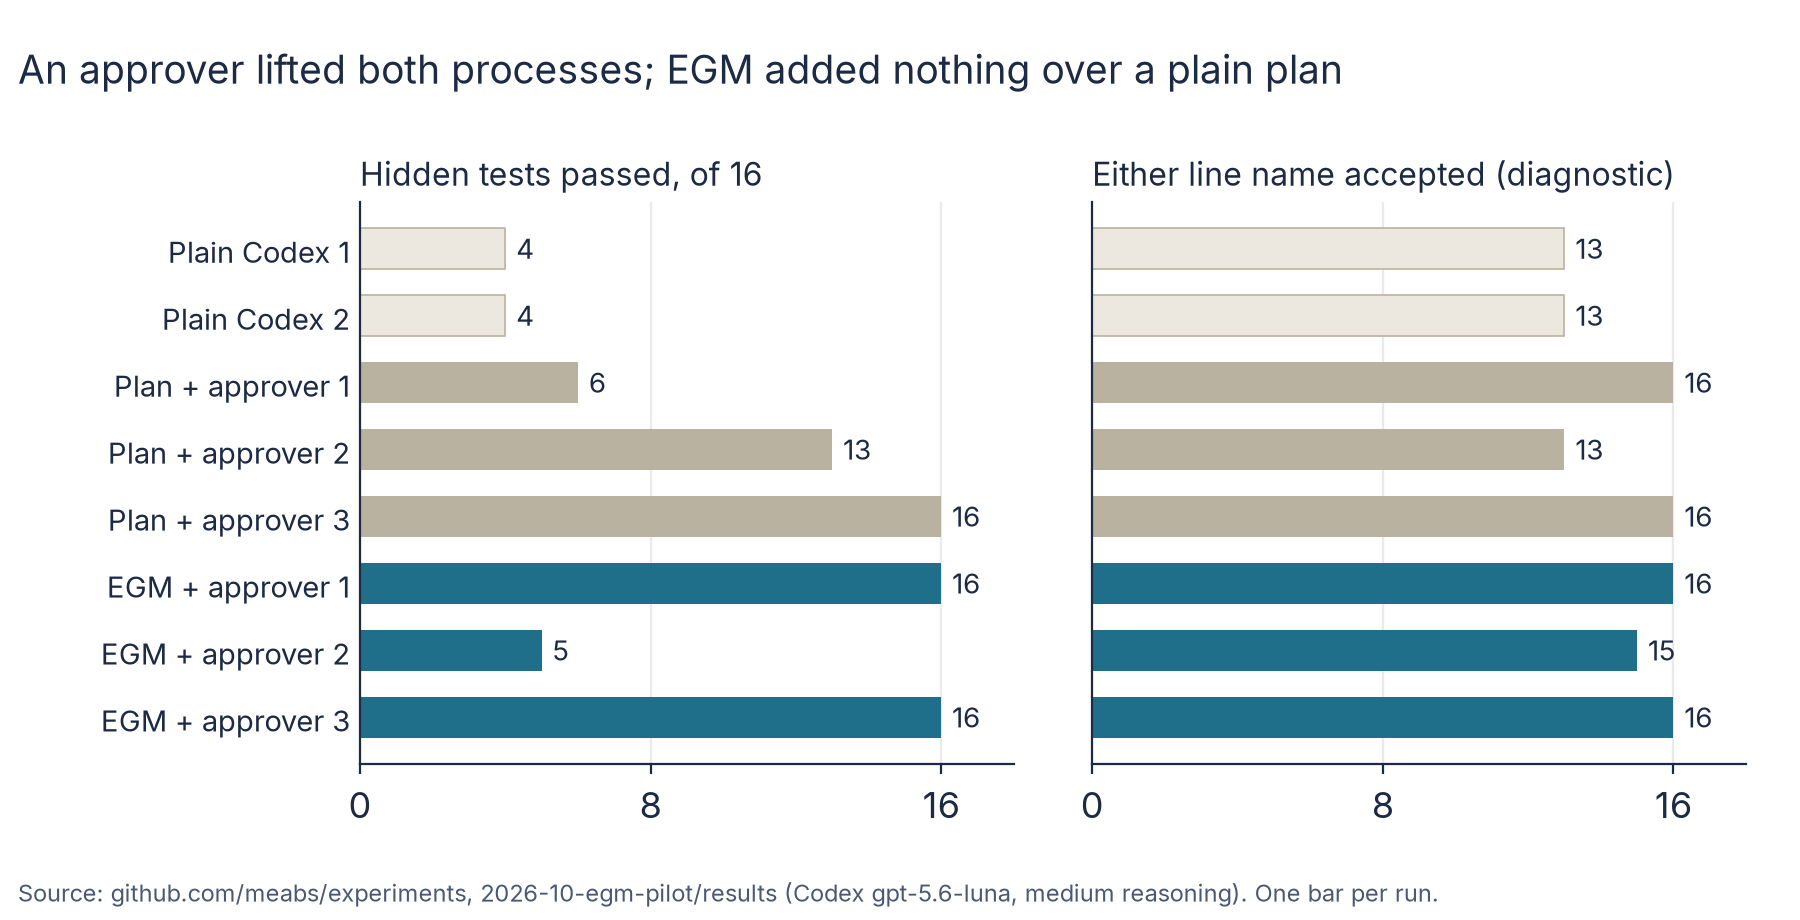
  • EGM-1A Claude approver reviewing the design before the build lifted Codex on a hard feature: three of six approver runs passed all 16 hidden tests, against 4 of 16 in both runs of plain Codex at the same effortapprover runs 16, 5, 16, 6, 13, 16 vs plain 4, 4
  • EGM-2EGM did no better than a plain plan reviewed by the same kind of approver, and cost about five times as much in Codex usage12.3 vs 11.7 of 16; $0.95 vs $0.19
  • EGM-3The score followed one sentence in the approved design, naming the cart's discount line "discount" as the task asks. Every run whose design said so scored 13 or 16; the two that did not scored 5 and 6. The name always came from the approver, never from EGM's reviewers13 to 16 vs 5 and 6
  • EGM-4Without an approver's judgement, EGM's thorough designs did not help: built at low effort they produced skeletons (3 and 1 of 16), and built at medium effort they scored 4 of 16, the same as plain Codex with the task alone3, 1 (low); 4, 4 (medium) vs 4, 2 (low); 4, 4 (medium)

Experiments

5 experiments

Harmful errors, lower is better, of 20 genuine threats and 22 harmless cases: one Luna agent 5 and 16; three voting 7 and 15; three after peer review 7 and 22; one agent with the same token budget 4 and 16; Sol reviewing the team 2 and 17; Sol alone 2 and 18. Of 42 falsified cases, right, sent for investigation and harmful: three voting 20, 0, 22, and with a can't-tell answer allowed 13, 11, 18; peer review 13, 0, 29, and with can't-tell allowed 8, 19, 15.

Controlled trial · TH

Three AI agents agreed. Did that make them right?

When security evidence has been tampered with, does a team of AI agents catch the error, repeat it, or make it worse, and does a stronger model reviewing the team's work fix it?

AI agents triaged security alerts whose evidence contained one false fact, contradicted by another record. A vote of three agents did no better than one. After reading each other's conclusions, all three escalated every harmless alert with conflicting records. A stronger model reviewing the team rarely overruled it. Allowing a "can't tell, investigate" answer halved the peer-reviewed team's harmful errors by sending cases to a human.
Difference in percentage points, 95% interval

Controlled trial · SPS

Does splitting a feature across coding agents beat one agent?

When a planner splits a feature into parts for coding agents working at the same time, does the team get more of it right than one agent, and does giving each coder only its part's requirements lose details at the joins?

A planner split each of six features into three parts, and three Codex coders built them at the same time. Whether each coder saw only its own part's requirements or the whole task, the team passed no more of the hidden acceptance tests than one agent did (61.6% and 52.9% against 62.4%), at 2.3 to 2.5 times the cost and with no saving in time. The split added a new failure: parts that didn't fit, so the application wouldn't start.

Difference in percentage points, 95% interval

Controlled trial · SWT

Does a team of coding agents beat one agent?

Does a team of coding agents (planner, coder, reviewer) get more of a feature right than one agent, and does any gain survive when one agent gets the same spend?

I gave Codex six feature tasks, either alone or as a team: a planner, a coder and a reviewer. One agent passed 56.8% of the hidden acceptance tests; the team passed 25.7%, at higher cost. The reason was the hand-off: only the planner saw the task, and its summary lost the details. Giving every agent the task file brought the team level with one agent (54.1%), still at higher cost.

Difference in percentage points, 95% interval

Controlled trial · DJ

Can an AI reviewer tell a broken change from a working one?

Shown a task and the change a coding agent made for it, can a model tell whether the change passes the hidden tests, and does the agent's own success report sway it?

Shown a task and a coding agent's change, gpt-5.6-luna called 57 of 96 right, no better than tossing a coin. The agent's own success report did not sway it, a doubtful one made it reject more of everything, and its confidence meant nothing.

Hidden tests passed of 16, one bar per run: plain Codex 4 and 4; plan plus approver 6, 13, 16; EGM plus approver 16, 5, 16

Pilot · EGM

Spec first with the Elephant-Goldfish Model, and an AI approver (pilot EGM)

Does writing a spec with Google's Elephant-Goldfish Model before any code is written make a coding agent build a hard feature more correctly, and how much of any gain comes from the person who approves the spec?

On a hard feature, a Claude approver reviewing the design lifted Codex from 4 of 16 hidden tests to as many as 16, whether the design came from Google's Elephant-Goldfish spec process or from a plain plan. EGM added nothing over the plain plan, at about five times the cost. A pilot: three runs per arm.

Other topics: Measurement, Context, Verification, Safety and cost, Skills, Briefs, Parallel, Harness