4. One verifiable change at a time
Free to read on the web. October 2026 PDF · Updates
Hand an agent one change you can verify at a time. A whole feature is too big a unit. Every agent runs the same loop (plan, act, observe, verify) whether you watch it or not, and the quality of the whole thing depends on two levers you control: how big each step is, and how good the verify step is. This chapter is about the first lever, and about watching one complete loop end to end. Chapter 5 is about the second.
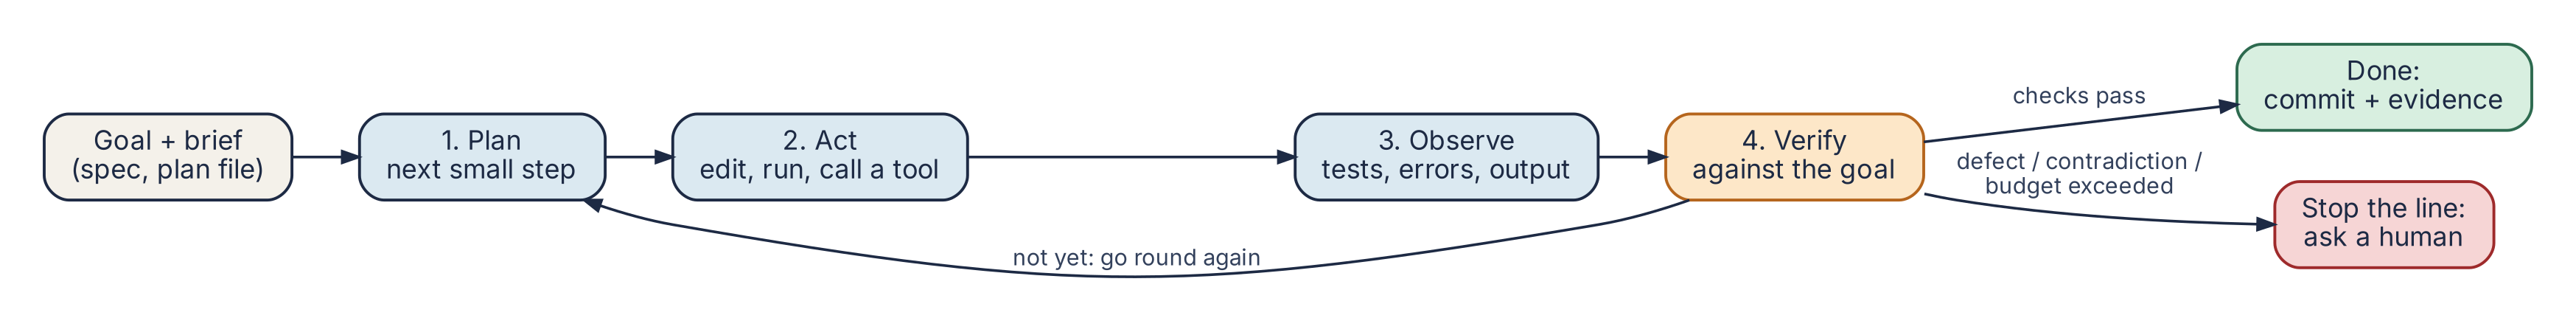
Worked example, stage 4: one complete loop
Section titled “Worked example, stage 4: one complete loop”Here is the availability change as a single loop: what an agent would read, change and check at each step. The commands and their output are real (from the worked example’s reproduce.sh); the sequencing shows how an agent should work.
| Step | Reads | Changes | Checks |
|---|---|---|---|
| 1. Orient | AGENTS.md, docs/brief.md, app/main.py, app/clients/catalogue.py, tests/ |
Nothing | Runs bash scripts/test.sh: contract fresh, 2 passed |
| 2. Facts | contracts/inventory.openapi.yaml 2.1.0 |
Nothing | Notes the path /v2/stock/{sku} and fields on_hand, reserved |
| 3. Client | The catalogue client as a pattern | Adds app/clients/inventory.py |
A test that parses the contract’s own example |
| 4. Red | The brief’s acceptance criteria | Adds tests/test_availability.py |
Runs it: new endpoint tests fail |
| 5. Green | The failures | Adds the route in app/main.py |
Runs bash scripts/test.sh: all pass |
| 6. Real use | — | Nothing | Runs both services, calls the endpoint (Chapter 5) |
| 7. Report | The command log | Nothing | Writes the status line from the log (Chapter 5) |
Step 1, before any change (genuine output):
== contract freshnessok: pinned 2.1.0, provider publishes 2.1.0== tests.. [100%]2 passed in 0.58sStep 4, red: the client exists, the endpoint doesn’t.
FAILED tests/test_availability.py::test_in_stock - assert 404 == 200FAILED tests/test_availability.py::test_all_reserved - AssertionError: assert...FAILED tests/test_availability.py::test_inventory_outside_contract_is_502_not_a_guessFAILED tests/test_availability.py::test_inventory_unreachable_is_502 - Assert...4 failed, 3 passed in 0.38sLook at the three that passed. One is the client’s contract test, which should pass. The other two are the 404 cases, and they passed because the route didn’t exist yet: FastAPI returns 404 for an unknown path. They prove nothing at this point, and a careful reviewer should ask for them to check the error detail as well as the status. That’s what a red run is for: it shows you which tests can’t fail.
Step 5, green. The whole behavioural change is fourteen lines in app/main.py:
@app.get("/products/{sku}/availability")def read_availability(sku: str): if catalogue.get_product(sku) is None: raise HTTPException(status_code=404, detail="unknown product") try: stock = inventory.get_stock(sku) except inventory.InventoryUnavailable: raise HTTPException(status_code=502, detail="inventory unavailable") from None if stock is None: raise HTTPException(status_code=404, detail="unknown to inventory") on_hand, reserved = stock available = max(on_hand - reserved, 0) return {"sku": sku, "available": available, "in_stock": available > 0}== contract freshnessok: pinned 2.1.0, provider publishes 2.1.0== tests......... [100%]9 passed in 0.29sEach step was small enough to check in seconds, and every check was a command rather than a judgement call. There isn’t much more to the technique than that.
Putting the prerequisite in the command
Section titled “Putting the prerequisite in the command”Case study: putting the prerequisite in the command. In one of my AgentTrialRig trials, agents doing a FastAPI change kept tripping over the same set-up step: the test database had no tables until migrations ran. Writing the step into
AGENTS.mdhelped, but some agents still ran the tests first, even after the wording was sharpened. A one-command test script that applied the migrations itself removed the problem in every run of that arm (AgentTrialRig README, “Verification claims”). Chapter 5 has the numbers. A step that must always happen belongs in a command. Three runs per arm gives a direction, though, and no measured saving.
The worked example’s scripts/test.sh is the same idea: one command that runs the freshness check and the tests, so neither depends on the agent remembering. Keep that command where the agent can’t edit it, though: Chapter 5 shows agents rewriting it to pass.
One thing per loop, and stopping the line
Section titled “One thing per loop, and stopping the line”Geoffrey Huntley, about his “Ralph” technique: “To get good outcomes with Ralph, you need to ask Ralph to do one thing per loop. Only one thing.” (Geoffrey Huntley, “Ralph Wiggum as a ‘software engineer’” (14 Jul 2025)) In its purest form Ralph is one line of shell that feeds the same prompt to an agent over and over; each pass reads the specs and a plan file, does the single most important unfinished item, runs the checks, updates the plan and exits, so state lives in files rather than in the model. Huntley is candid that it suits greenfield bootstrapping and that you should watch the loop. It works because each pass is one verifiable change. Harper Reed asks for steps “small enough to be implemented safely with strong testing, but big enough to move the project forward.” (Harper Reed, “My LLM codegen workflow atm” (16 Feb 2025)) Karpathy works in small increments for the same reason.
@poteto’s “Loops You Can Trust” borrows from lean manufacturing: “One key aspect of building trustworthy loops is that every stage can stop the line.” (lauren (@poteto), X Article “Loops You Can Trust” (24 Jun 2026)) A failing check, an unexpected diff size or a missing artefact should halt the loop and call a human, not be retried until it goes away. She also argues that autonomy is earned: run supervised first, fix the failure modes, then let it run alone. And “If a script can do it deterministically, use the script.” (lauren (@poteto), X Article “Loops You Can Trust” (24 Jun 2026)) For a large migration, do the first unit by hand, have the agent write a codemod plus a checker, and keep the agent for the exceptions: the prerequisite case study at a larger scale.
Some practitioners happily hand agents large tasks and get good results. The accounts of that which I have read describe a strong verification harness behind it. So the size of a safe step depends on how strong the check is. How confident the agent sounds doesn’t come into it.
Recommendation: size, stopping conditions and branches
Section titled “Recommendation: size, stopping conditions and branches”Before handing over a task, apply three canny little tests. Can “done” be stated as a check that runs in a few minutes? If not, split it. Will the diff be something I can actually review? Can I throw the whole thing away without tears? If not, it’s too big, or it needs a branch.
Before letting anything run unattended, write down its success condition (which checks, what evidence), its failure condition (how many attempts at one step), its danger conditions (contradictory requirements, a destructive operation, a change outside scope: stop immediately), and its budget (time and spend). Enforce them in the harness where you can. A loop without a stopping condition is a very expensive way of heating the room.
Work on a branch and commit each completed step. Each commit can then be reviewed, reverted or bisected, and the agent is good at the Git chores itself.
Try this on your repository
Section titled “Try this on your repository”- Take a task you’d normally give an agent in one go. Break it into steps where each step ends with a command that proves it (a test, a type check, a
curl). - Run it twice: once as one big prompt, once step by step with the check run after each step.
- Compare: how many corrections did you make, how big was the final diff, and how long did review take?
- For any step the agent got wrong more than once, ask whether a script or a check could make that step impossible to get wrong. If so, write it.
Checklist
Section titled “Checklist”- One verifiable change per loop iteration; state in files, not in the model.
- Write the failing test first and read which tests didn’t fail.
- Size each step so “done” is a check that runs in minutes.
- Any stage can stop the line; never auto-retry a defect away.
- Scripts and codemods for deterministic work; agents for judgement.
- Success, failure, danger and budget conditions before going unattended.
- Branch, and commit every completed step.